Maven & Minab: Untangling the Machinery of a Targeting Failure

The Strike and the Emerging Account
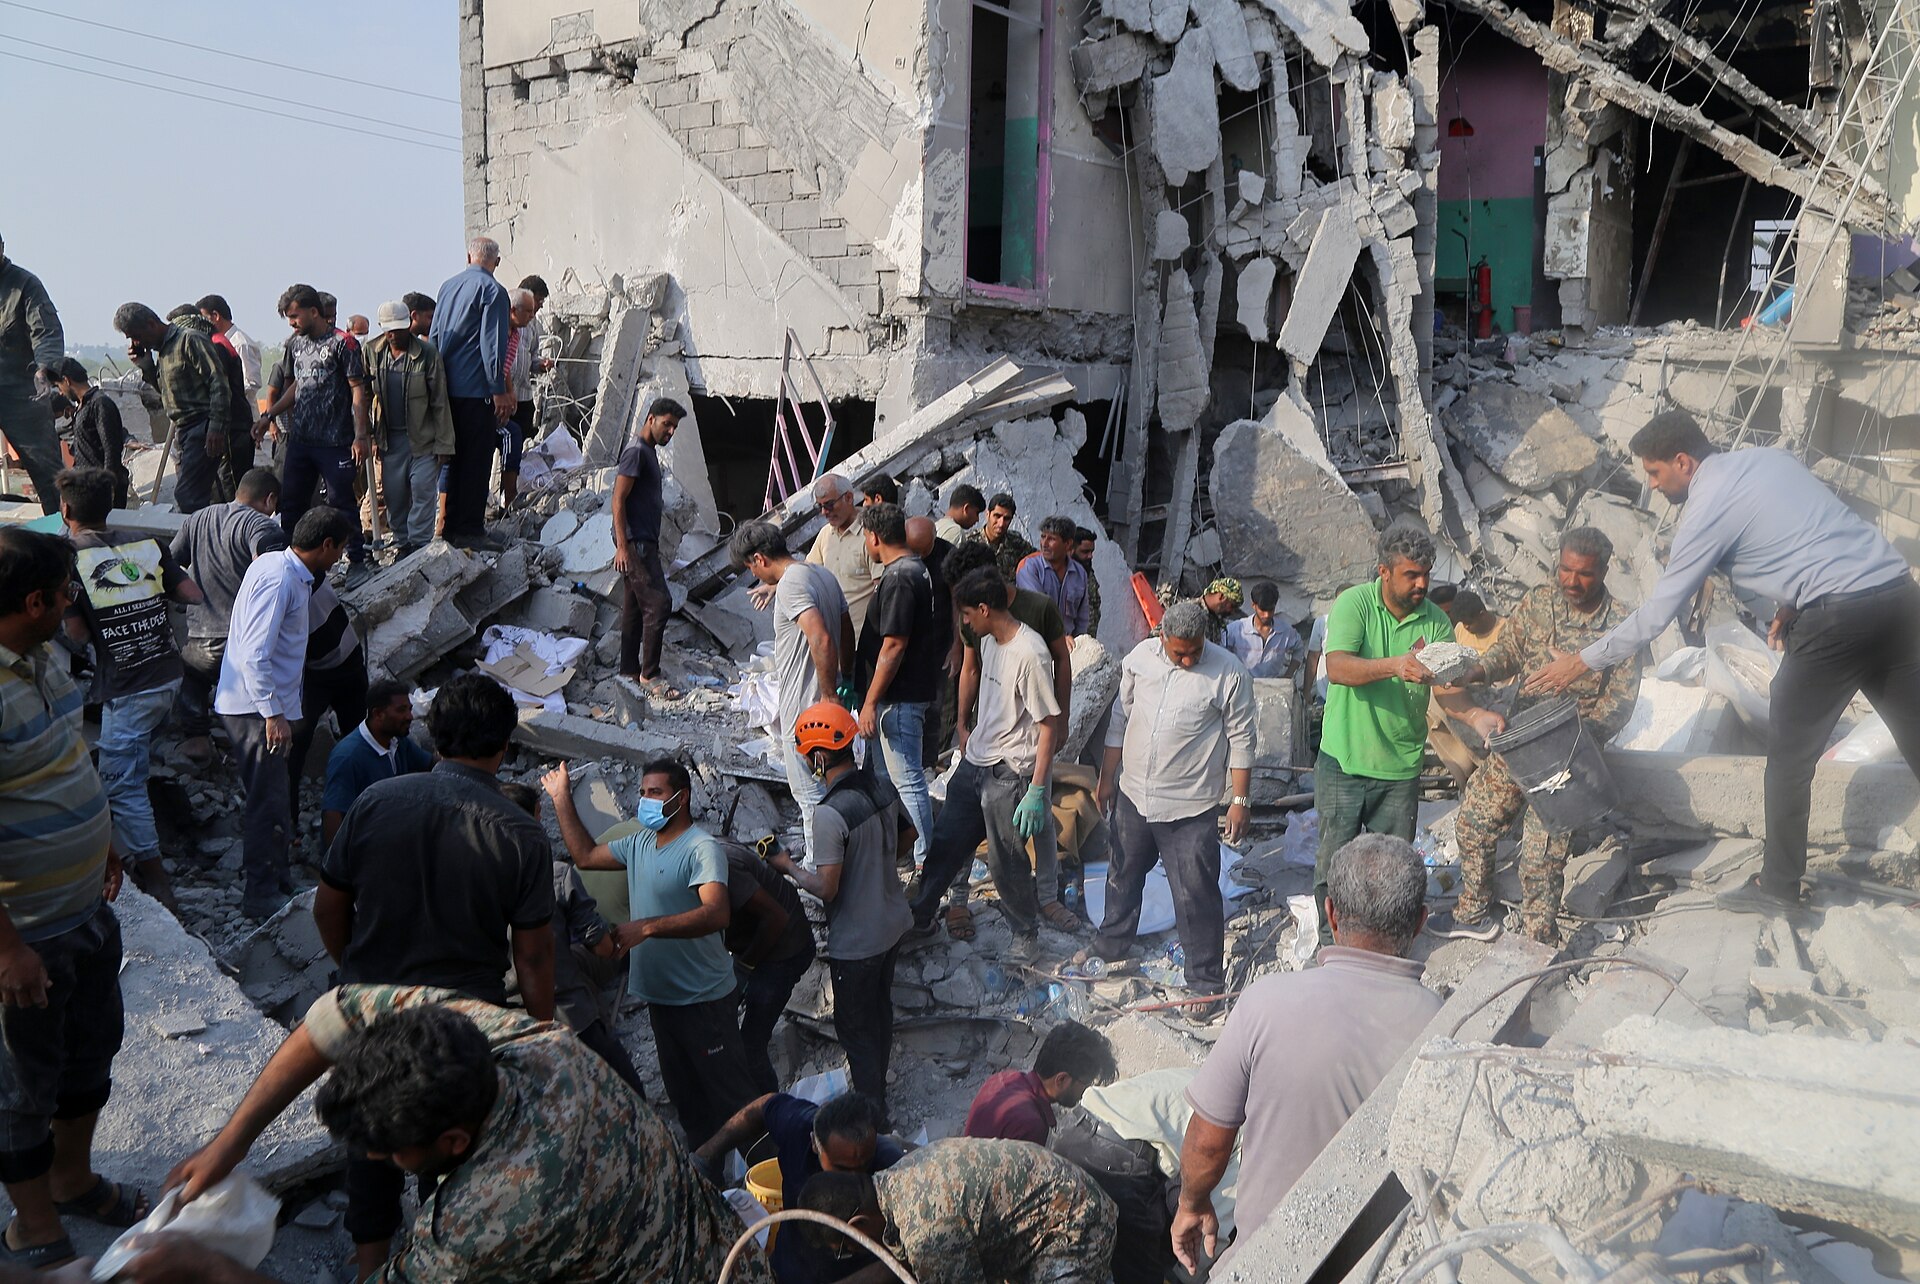
On February 28, 2026, an airstrike hit Shajareh Tayyebeh Elementary School in Minab, Iran. In June, Amnesty International reported that more than 150 people, including 120 children, had been killed. The attack raised an immediate question about how a school had entered the targeting process. Subsequent reporting has sharpened a second question: What did military personnel believe the software supporting that process had already checked?
Gizmodo’s account of Bloomberg’s September investigation describes excessive reliance on Maven among the contributing failures. According to the account, officials expected Palantir’s Maven Smart System to detect outdated records or conflicting intelligence. The site entered the platform under an outdated military designation and emerged as a recommended target for the opening day of the US-Israeli campaign against Iran on February 28, 2026. Palantir disputed that its software was at fault and maintained that responsibility for the underlying intelligence rested with the government.
These claims come from reporting on an unpublished investigation, not from a public official finding. They nevertheless identify a specific problem worth examining: the possibility that users assumed Maven had already verified information that others were still responsible for checking.
If that account holds, the significance extends beyond whether an algorithm malfunctioned. A platform may process supplied information as intended while its users misunderstand what the resulting recommendation establishes. The Minab controversy therefore brings a neglected dimension of human oversight into view: an approving officer’s judgment depends partly on their understanding of the work already performed by the people and systems upstream.
Epistemic Delegation Before Authorization
In an earlier Small Wars Journal article, I described epistemic delegation as states’ reliance on private systems to produce and organize the operational knowledge informing military action. Its central concern is influence before authorization. A firm does not necessarily need to exercise command authority to influence military decision-making. It is possible for decision-making authority to remain with military personnel, while privately developed systems still structure the information, classifications, and recommendations that those personnel use to identify threats and evaluate courses of action.
The original argument concerned security cooperation, where provider governments, recipient forces, and commercial firms participate in producing an operational picture. Minab invites an application within a state’s own military. Institutional arrangements may differ, but the underlying question persists: how does reliance on privately developed software affect what military personnel treat as sufficiently established to act upon?
This distinction matters because retaining human approval does not settle how a judgment was formed. An officer may retain discretion while relying on classifications or recommendations produced earlier in the workflow. None of this means the officer stopped making the decision. It means we need to understand what information—and what assumptions about that information—shaped the decision.
Minab also pushes the idea of epistemic delegation one step further. Beyond shaping what users see, a system may influence what they believe has already been verified. The question, then, is not only what Maven could do, but what its users thought it could do.
The Gap between Recommendation and Verification
The most consequential detail in the September reporting is the expectation that Maven would identify stale or contradictory intelligence. That expectation concerns the meaning of the output. A target appearing in a recommended list might mean only that it meets specified criteria using the information supplied. A user could nevertheless interpret its inclusion as assurance that relevant doubts have already been resolved. Those are different claims about what the system knows.
The mechanism is simple: the recommendation may have made uncertain intelligence look more settled than it really was. Information enters a workflow carrying assumptions and limitations; a recommendation leaves it appearing ready for action. Unless those limitations remain visible, users may attach confidence to the recommendation that the underlying evidence does not justify. Establishing whether this happened at Minab requires reconstructing what personnel saw, what they understood the output to mean, and which checks they performed themselves. The reporting gives us reason to ask these questions, but not enough evidence yet to answer all of them.
This concern is consistent with the National Institute of Standards and Technology’s AI Risk Management Framework. NIST treats AI risks as arising from interactions between technology, human behavior, and organizational context. Its discussion of human–AI interaction emphasizes clearly differentiated responsibilities and recognizes that people interpret system outputs differently. NIST’s framework points to the broader problem: knowing whether the software worked as designed tells us little about whether the decision process around it worked.
Palantir’s reported position makes the allocation of responsibility especially important. Government responsibility for intelligence quality can coexist with a need to investigate how a platform communicates the limits of that intelligence. The relevant questions include whether users received clear warnings, whether training distinguished recommendation from verification, and whether procedures assigned an identifiable person the remaining checks. None of those questions requires Maven itself to have malfunctioned. The failure may instead lie in the way the system was understood and used.
According to Bloomberg, after the strike Palantir added capabilities to Maven that re-review underlying intelligence for factors that could disqualify a target and flag inconsistencies for inaccuracies that human reviewers might have previously missed. The reported addition of intelligence-review safeguards after the strike warrants similar care. A subsequent improvement does not, by itself, demonstrate an earlier breach or establish what would have prevented the attack. It does identify a function whose place in the workflow deserves scrutiny. Why was it previously left outside the platform, who was expected to perform it, and did users understand that division?
The provisional lesson is that epistemic delegation can encompass assumptions about verification as well as reliance on information. Human review becomes vulnerable when personnel misunderstand the evidentiary work behind the recommendation they are reviewing. Determining how that misunderstanding arose is essential to explaining the respective contributions of the software, its users, and the organizations governing both.
Responsibility Across the Targeting Process
An explanation centered on misplaced trust in Maven must also account for the intelligence and organizational processes surrounding its use. Reuters reported in June that officials preparing targeting packages appeared to have relied on outdated intelligence. This raises a question that precedes the platform’s involvement: why did the information entering the targeting process still identify the site as a military facility?
The answer matters for assigning responsibility. Investigators need to distinguish the initial intelligence error from its subsequent transmission, presentation, and acceptance. The relevant failures could involve database maintenance, incomplete information sharing, inadequate review, or misunderstood software capabilities. Several could have operated together. Establishing that Maven influenced the process would not establish that its contribution was the sole or decisive cause.
The strongest alternative explanation is that Minab resulted principally from familiar intelligence and command failures that could have occurred without AI. That possibility deserves serious consideration. Epistemic delegation matters here only if Maven changed what people did—how closely they checked the intelligence, what they thought a recommendation meant, or who they believed was responsible for verification. Otherwise, the platform’s presence may explain less than its prominence in public debate suggests.
Conversely, software need not malfunction to contribute to an unsafe process. A system can meet its technical specifications while being deployed under mistaken assumptions about what those specifications guarantee. So responsibility depends on two questions: who was supposed to check what, and did the people using Maven actually understand that division? The military’s responsibility for authorizing force remains central; questions about procurement, design, training, and implementation concern how it discharged that responsibility. The purpose of tracing the entire process is to identify the decisions and omissions that made the outcome possible, including those occurring well before final approval.
Making Verification Explicit
The practical response should begin by making verification responsibilities explicit. Every consequential stage of an AI-supported targeting workflow should identify what the system checks, what it leaves unresolved, and who must complete the remaining work. Training should test whether personnel understand those boundaries. A general instruction to exercise human judgment is insufficient if users misunderstand the evidentiary status of the information they are judging.
The NIST AI Risk Management Framework provides a useful starting point through its emphasis on documented oversight, operator proficiency, and risks associated with third-party data and software. Applied to targeting, these principles support interfaces that distinguish a recommendation from completed verification. Users should be able to identify the age and provenance of relevant intelligence, unresolved contradictions, and the checks that remain outstanding.
Record preservation is equally important. Investigators need to reconstruct which data and system versions informed a recommendation, what information appeared to reviewers, and what actions those reviewers took. Such records would help distinguish an erroneous input from a misleading presentation, a misunderstood output, or a consciously accepted uncertainty. Appropriate investigators require access to that evidence even when operational security limits public disclosure.
Finally, organizations should evaluate the combined performance of personnel and software under realistic conditions. Exercises should introduce outdated records and contradictory evidence, then assess whether users detect the problem, understand their responsibilities, and interrupt the process when necessary. Faster production of recommendations should be assessed alongside the quality of their review.
Minab’s full causal account remains to be established publicly. The reported verification gap nevertheless identifies a concrete governance problem: a human can approve a strike while relying on an AI-enabled targeting system they do not fully understand. Effective oversight should therefore examine not just who makes final decisions, but also how the recommendations that inform such decisions are deemed to be trustworthy in the first place.